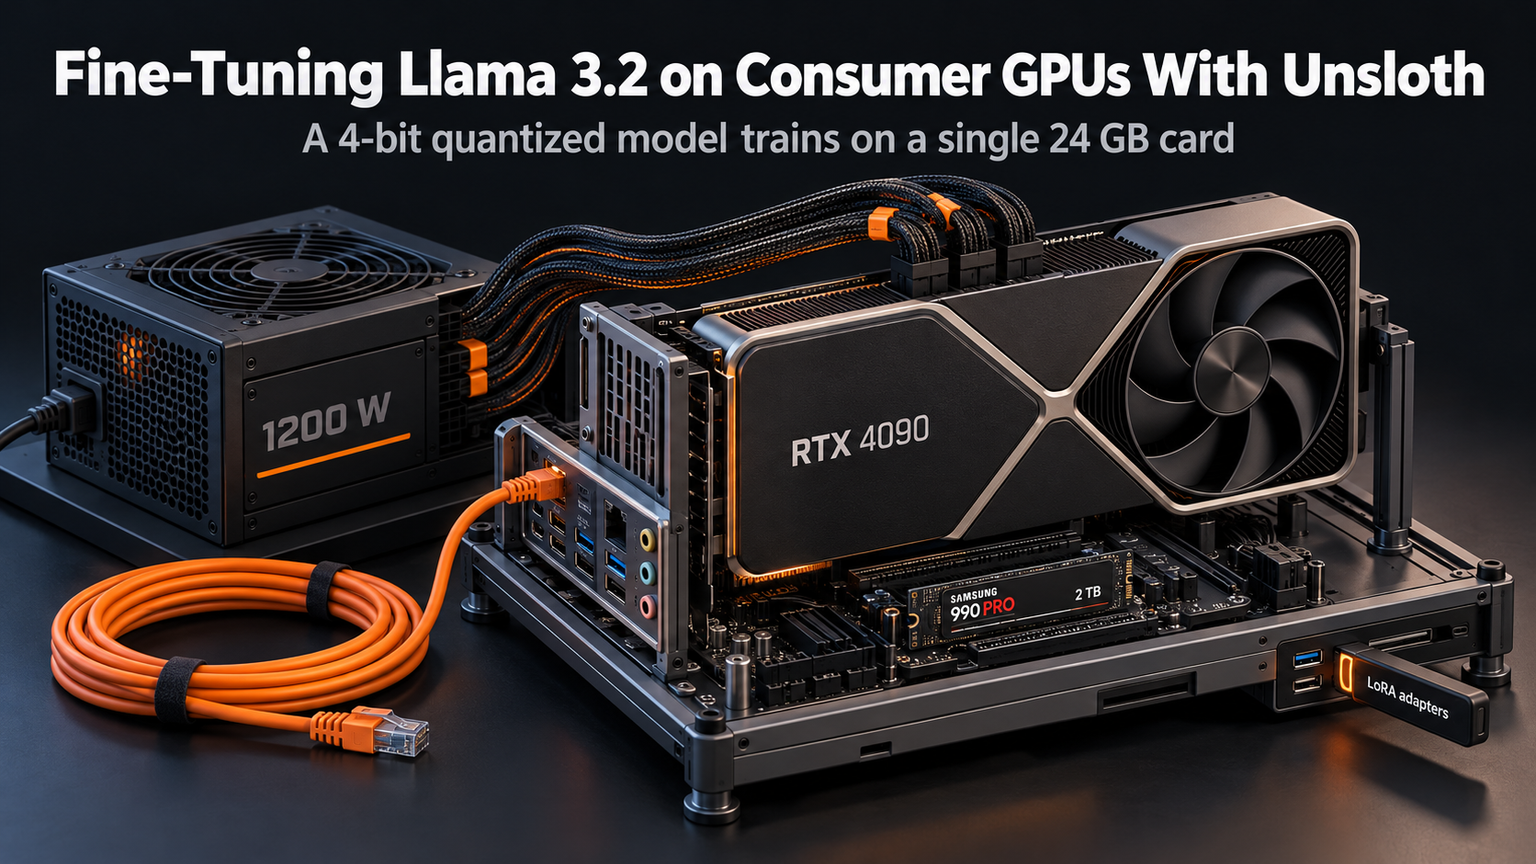
Running a capable LLM locally used to mean renting A100s or settling for 7B models that crawl on consumer silicon. Llama 3.2 3B changes that calculus. At 3 billion parameters, it fits comfortably on a single RTX 4090 with room to spare for fine-tuning, not just inference. Here is the practical path to adapting it to your data without melting your VRAM.
Why 3.2 3B Is the Sweet Spot
Meta's 3.2 release isn't just a size reduction. The 3B variant uses Grouped Query Attention (GQA) and a 128k context window, inheriting architecture upgrades from the 70B teacher model during distillation. Benchmarks show it punching above its weight class on MMLU and GSM8K, often matching Llama 3.1 8B instruct scores. For fine-tuning, the parameter count means full-parameter training is technically possible on 24GB VRAM, but LoRA remains the smarter default.
Hardware & Software Stack
| Component | Spec |
|---|---|
| GPU | NVIDIA RTX 4090 (24GB VRAM) |
| Driver | 550+ / CUDA 12.4 |
| Framework | PyTorch 2.4+, Unsloth or Axolotl |
| Quantization | 4-bit NF4 (QLoRA) |
| Precision | bf16 compute, fp32 master weights |
💡
TipUse Unsloth for 2x speedup and 60% less VRAM vs stock Hugging Face Trainer. It fuses kernels and handles 4-bit optimization natively.
QLoRA Config That Fits
This config peaks around 21GB VRAM. Batch size 2 with gradient accumulation 4 simulates an effective batch of 8. Drop max_seq_length to 1024 if you OOM on longer contexts. The adamw_8bit optimizer from bitsandbytes shaves another 1.5GB versus AdamW fp32 states.
Data Prep: Quality Over Quantity
3B models overfit fast. Curate 1,000–5,000 high-quality examples rather than dumping 50k noisy rows. Format as ShareGPT or Alpaca:
⚠️
WarningStrip PII and deduplicate. Run `text-dedup` with MinHash (threshold 0.8) before training. Garbage in, garbage out hits harder at 3B.
Training Loop & Monitoring
Launch with unsloth train or axolotl train config.yml. Expect ~45 min/epoch on 3k samples. Watch three metrics:
| Metric | Target | Action if Off |
|---|---|---|
| Train Loss | < 1.5 by epoch 2 | Increase LR or check data quality |
| Grad Norm | < 1.0 stable | Clip at 1.0, reduce LR |
| VRAM Usage | < 22GB | Drop seq_len or batch_size |
Log to Weights & Biases or TensorBoard. Save checkpoints every 500 steps. Merge LoRA adapters post-training:
Validation Checklist Before Deploy
Run a quick eval harness:
ℹ️
NoteIf outputs hallucinate or repeat, re-run with higher <code>lora_dropout</code> (0.1) or lower <code>learning_rate</code> (1e-4). 3B is sensitive.
✦
Ship It
Quantize the merged model to GGUF (Q4_K_M) via llama.cpp for CPU inference or Ollama bundling. Push the LoRA adapter to Hugging Face Hub — it's 30MB, versionable, and reusable. Your 4090 just became a sovereign LLM factory. Next weekend, try the same pipeline on a domain-specific corpus: legal clauses, SQL generation, or your company's internal wiki. The model is small. The leverage is not.